First, though, let me tell you about the time I decided to create a golden age and how that went.
10.1 The path toward a golden age of opinion survey data
When I began conducting opinion surveys, I copied the methods that were familiar to me. Specifically, I ran one-shot surveys with observations massed over a short period of time. This approach has one strong advantage — one gains a clear snapshot of the population at one moment in time.
But the research questions I was most interested in answering involved change over time. I needed my observations spread out over the calendar. In the case of AI and public opinion, I was trying to catch a moment. Specifically, I wanted to capture the before and after of the artificial intelligence Three Mile Island or its China Syndrome. I was fairly sure there would be some public AI freakout event, but I had no idea when it would happen.
The idea was to do the opposite of one-shot, massed survey snapshots. Instead, I wanted to capture many frames in the movie of public opinion on AI.
I was accustomed to daily data from my hobby of stock watching and my professional work researching social media. I looked into commissioning daily surveys from commercial providers and quickly discovered that would not be possible in my budget. So I decided to build my own daily survey system.
The Social Science Dashboard Inator was the result. I wrote code to combine all the necessary parts: online surveys, respondent recruitment, and data distribution.
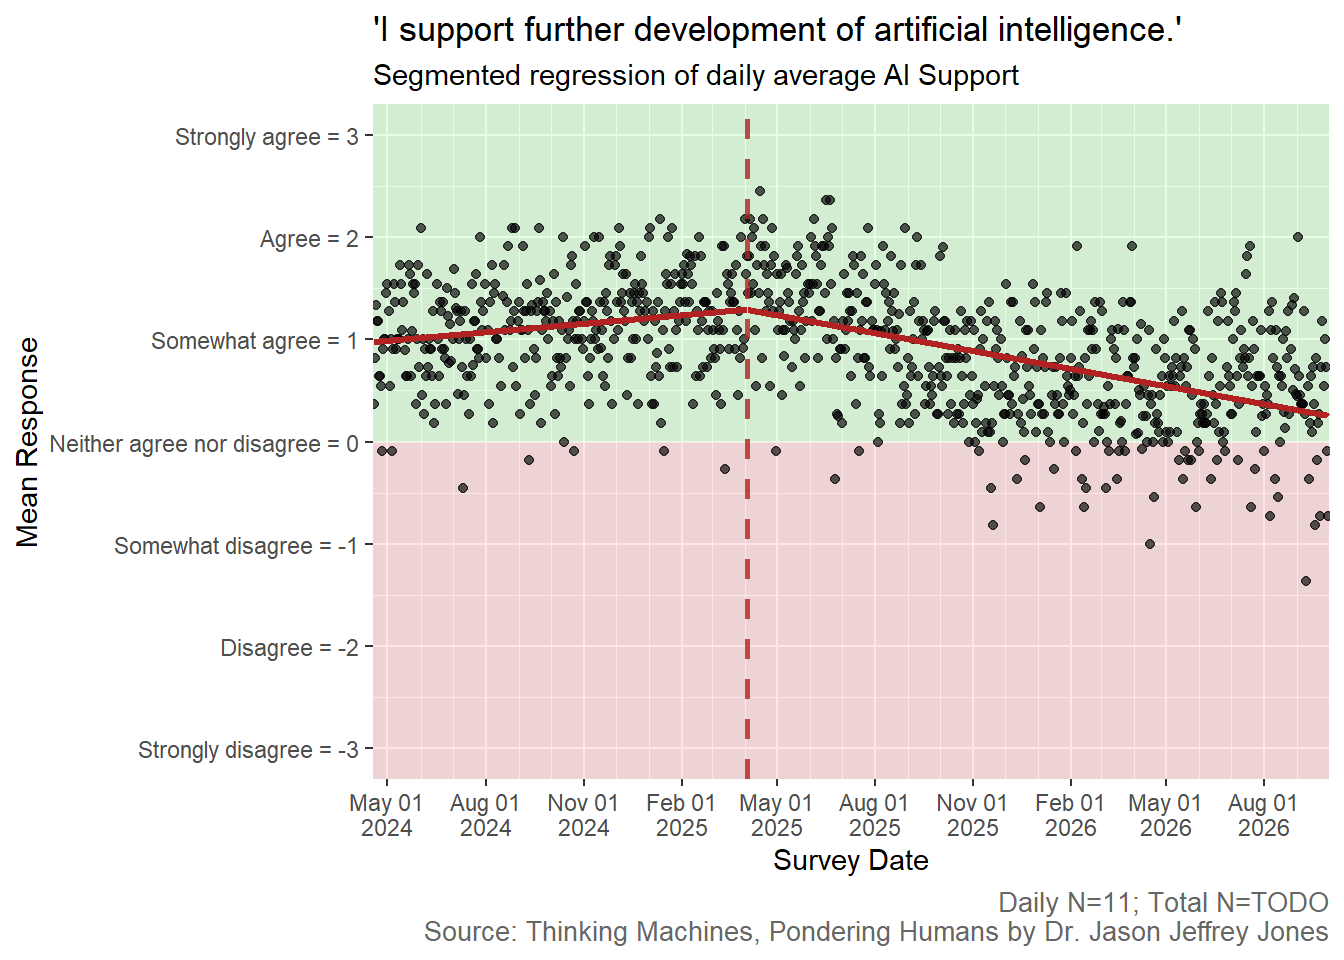
I named the first dashboard AI Daily by Jason Jeffrey Jones Productions and began collecting data daily in April, 2024. The main goal was to measure support and opposition to further development of artificial intelligence. The headline result? AI Support increased from April 2024 through April 2025, then began a slide toward opposition that continued through September 2026.
Code
# The file jjjp-ai-support-daily-2026-10-16.csv contains responses from daily AI Support surveys.# Download the file from a public open science repository at https://doi.org/10.5281/zenodo.20399282aiDaily =read_csv("data/jjjp-ai-support-daily-2026-10-16.csv")dailyStartDate =as.Date("2024-04-18")aiDaily = aiDaily %>%# A small number of respondents skip the Support question. (Two in the first two years.)filter(!is.na(Support)) %>%# Cut off partial month data.filter(Obs_Date <as.Date("2026-10-01")) %>%# Remove the weekly data that precedes daily sampling.filter(Obs_Date >= dailyStartDate)# Create a coalesced Party variable.aiDaily = aiDaily %>%mutate(Party = Party_1) %>%mutate(Party =if_else(Party_2 =="Lean Democratic", "Democrat", Party, missing = Party) ) %>%mutate(Party =if_else(Party_2 =="Lean Republican", "Republican", Party, missing = Party) )# Create a more concise Generalized_Trust variable.aiDaily = aiDaily %>%mutate(Generalized_Trust =ifelse(Generalized_Trust =="Most people can be trusted.", "Trusting", "Careful") ) %>%mutate(Generalized_Trust =factor(Generalized_Trust, levels =c("Careful", "Trusting")) )# Create a number of days since first daily variable.aiDaily = aiDaily %>%mutate(Days_Since_Day_One =time_length(interval(dailyStartDate, Obs_Date), "days") )dailyMostRecentDate =max(aiDaily$Obs_Date)book_source_caption =paste0("Source: Thinking Machines, Pondering Humans by Dr. Jason Jeffrey Jones")this_caption <-paste0("Daily N=11; Total N=TODO\n", book_source_caption)###### Segmented regression to find turning point in Support.####library(segmented)# Create daily means dataset.aiDailyByDate <- aiDaily %>%filter(Obs_Date >= dailyStartDate) %>%filter(!is.na(Support)) %>%group_by(Obs_Date) %>%summarise(Support_Mean =mean(Support),n =n(),.groups ="drop" ) %>%mutate(Days_Since_Day_One =as.numeric(Obs_Date - dailyStartDate) )# Fit ordinary linear model first.aiDailyLM <-lm( Support_Mean ~ Days_Since_Day_One,data = aiDailyByDate)# Davies test: evidence for a change in slope somewhere in the time series.daviesTest <-davies.test( aiDailyLM,seg.Z =~ Days_Since_Day_One)#daviesTest# Use segmented to label the breakpoint.# Initial breakpoint guess, based on prior analysis in 2025.# initialBreakpointDay does not force the answer; it just helps the optimizer start in a sensible place.initialBreakpointDate <-as.Date("2025-06-05")initialBreakpointDay <-as.numeric(initialBreakpointDate - dailyStartDate)# Fit segmented regression.aiDailySegmented <-segmented( aiDailyLM,seg.Z =~ Days_Since_Day_One,psi = initialBreakpointDay)#summary(aiDailySegmented)# Slopes before and after breakpoint.#slope(aiDailySegmented)# Extract estimated breakpoint.breakpointDay <- aiDailySegmented$psi[1, "Est."]breakpointDate <- dailyStartDate +round(breakpointDay)#breakpointDay#breakpointDate# Create prediction data to overplot segmented regression on data points.segmentedPredictions <- aiDailyByDate %>%mutate(Segmented_Fit =predict(aiDailySegmented, newdata = aiDailyByDate),Segment =if_else( Days_Since_Day_One <= breakpointDay,"Before breakpoint","After breakpoint" ) )# Plot daily points plus segmented regression.dailySupportSegmentedPlot <-ggplot( aiDailyByDate,aes(x = Obs_Date, y = Support_Mean)) +annotate(geom ="rect",xmin =as.Date(-Inf),xmax =as.Date(Inf),ymin =0,ymax =Inf,fill ="green",alpha =0.1 ) +annotate(geom ="rect",xmin =as.Date(-Inf),xmax =as.Date(Inf),ymin =-Inf,ymax =0,fill ="red",alpha =0.1 ) +geom_point(alpha =0.65) +geom_line(data = segmentedPredictions,aes(x = Obs_Date, y = Segmented_Fit, group = Segment),color ="firebrick",linewidth =1.2 ) +geom_vline(xintercept = breakpointDate,linetype ="dashed",color ="firebrick",linewidth =0.9,alpha =0.8 ) +ggtitle("'I support further development of artificial intelligence.'","Segmented regression of daily average AI Support" ) +xlab("Survey Date") +ylab("Mean Response") +labs(caption = this_caption) +theme(plot.caption =element_text(size =10,color ="#666666",hjust =1 ) ) +scale_x_date(limits =c(dailyStartDate, dailyMostRecentDate),breaks =seq(as.Date("2024-05-01"), dailyMostRecentDate, by ="3 months"),minor_breaks =seq(as.Date("2024-05-01"), dailyMostRecentDate, by ="1 month"),date_labels ="%b %d\n%Y",expand =expansion(add =1) ) +scale_y_continuous(limits =c(-3, 3),breaks =-3:3,labels =c("Strongly disagree = -3","Disagree = -2","Somewhat disagree = -1","Neither agree nor disagree = 0","Somewhat agree = 1","Agree = 2","Strongly agree = 3" ) )detach("package:segmented", unload =TRUE)detach("package:MASS", unload =TRUE)# End segmented regression analysisdailySupportSegmentedPlot
Figure 10.1: Daily estimates of AI Support from surveys of American adults. A segmented regression analysis indicated one change in slope. AI Support increased from April 2024 through April 2025, and decreased afterward. The red vertical dashed line shows an estimated inflection date.
In Covid-19 times, I consulted online dashboards every day. I wanted to know the prevalence of new cases in the US, in New York, in my county. It was reassuring to know cases were being tracked and comforting to see the growth slow, stop and reverse into decline. It made me wonder why (as a computational social scientist focused on big data) there was nothing like that to be found in my professional life.
I decided to turn my sporadic survey habit into a daily ritual. I invested the time to write code to automate that daily ritual. My publishing company invested the money to pay survey respondents. As of October 1st, 2026, the same survey has run 888 times. 9,883 American adults have expressed their level of AI Support. At the current rate of sampling eleven people per day, the dashboard collects more than 330 each month or 4,000+ observations per year.
Just like presidential approval polls track the population’s attitude toward the President, my survey tracks the population’s attitude toward artificial intelligence. Call it an AI Vibe Check. Even if it weren’t my own creation, it would be my favorite data source, due to all these positive features:
Consistency. The survey stays the same. Comparisons across time and groups are apples-to-apples.
Persistence. New data arrives daily. There’s no wait for future funding or others’ attention.
Transparency. Anonymized microdata is free to download. My analysis code is open source. Anyone can replicate, remix and extend what I’ve built.
Automated. This one is huge. Most days, I am busy with other things, and I don’t think about the survey or results at all. And yet, new data and results accumulate!
10.3 Generalization: the Ryerson Project to Nowcast Everything Daily
Estimating AI Support in the American population is cool. But you know what would be really cool? Nowcasting Everything Daily. Let me explain.
Nowcasting began in meteorology. Meteorologists are valued because they can forecast the weather. But forecasts are predictions, and predictions about the future are notoriously difficult. Much easier is to precisely measure the present. That is helpful, because many systems (even complex systems like humans and the atmosphere) usually do not change much from moment. Knowing the present state makes a prediction five minutes into the future easy.
This is the motivation to nowcast. Measure the present consistently, persistently and precisely, and you accumulate a series of observations. The series becomes your evidence base for making statements about the past and predictions for the future.
In science, such data are called time series. In the case of AI Daily, I created daily time series of AI Support estimates. It is my opinion that we do not have enough time series data yet to perform rigorous, evidence-bound social science. To address this deficit, I have devoted all of my research time and funds to creating daily time series.
I want to measure the attitudes, beliefs and behavior of people beyond just their AI Support. That is why I built and maintain the Ryerson Project. The goal of the Ryerson Project is to Nowcast Everything Daily. At the heart of it is a daily omnibus survey. Hundreds of American adults per month respond to dozens of survey items. Every day, many time series of persistently, consistently estimates accumulates.
The idea of social science dashboarding is in its infancy. I am excited for more curious minds to turn their attention this way.
10.4 Analysis, Visualization and Interpretation
This is the part of the chapter where I usually show you visualizations to explain the survey data. No need to break tradition, we’ll do that. However, let me point out that the results below are going into a book, which means they will be frozen in time. Data collection, the time series, and the dashboard lives on; go see the live data, too!
10.4.1 Among US adults, support for more AI development peaked in 2025.
Return to Figure 10.1 for the headline result. AI Support increased at first, but the trend reversed. Average support is lower now than when I began collecting data in April 2024.
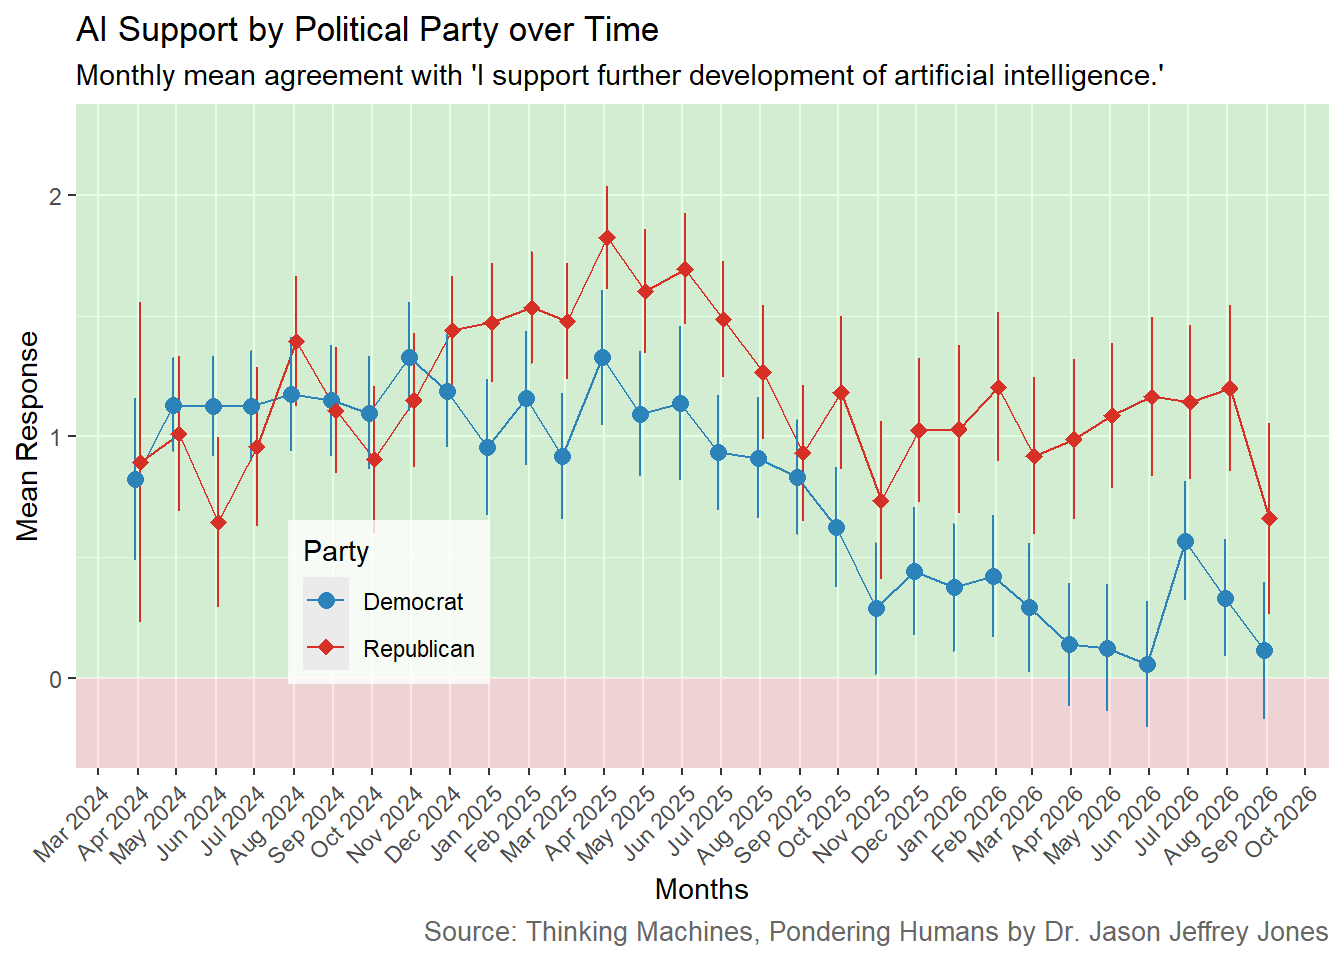
10.4.2 Political polarization emerged following November 2024.
Code
# Coarsen to monthly resolution.# Instead of raw Obs_Date, mark each observation with the month.aiDaily = aiDaily %>%mutate(Month =floor_date(Obs_Date, "month"))# Number the months. That will be useful for regression.aiDaily = aiDaily %>%mutate(Month_Number =time_length(interval(min(Month), Month), "months") )# Visualize polarization results.point_dodge <-position_dodge(width =8)aiDaily %>%select(Month, Party, Support) %>%filter(Party %in%c("Democrat", "Republican")) %>%group_by(Month, Party) %>%summarise(Support_Mean =mean(Support), n =n(),SE =sd(Support, na.rm =TRUE) /sqrt(n),CI_Lower = Support_Mean -qt(0.975, df = n -1) * SE,CI_Upper = Support_Mean +qt(0.975, df = n -1) * SE,.groups ="drop" ) %>%ggplot(aes(x = Month, y = Support_Mean, color = Party, group = Party)) +annotate("rect", xmin =as.Date(-Inf), xmax =as.Date(Inf),ymin =0, ymax =Inf, fill ="green", alpha =0.1) +annotate("rect", xmin =as.Date(-Inf), xmax =as.Date(Inf),ymin =-Inf, ymax =0, fill ="red", alpha =0.1) +geom_path(position = point_dodge) +geom_errorbar(aes(ymin = CI_Lower, ymax = CI_Upper),width =0.2,position = point_dodge ) +geom_point(aes(shape = Party, fill = Party),size =2.7,stroke =0.5,position = point_dodge ) +ggtitle("AI Support by Political Party over Time","Monthly mean agreement with 'I support further development of artificial intelligence.'" ) +xlab("Months") +ylab("Mean Response") +labs(caption = book_source_caption) +theme(plot.caption =element_text(size =10,color ="#666666",hjust =1 ) ) +scale_x_date(date_breaks ="1 month", date_labels ="%b %Y",minor_breaks =NULL, guide =guide_axis(angle =45) ) +scale_y_continuous(limits =c(-0.25, 2.25), breaks =-1:3) +scale_shape_manual(values =c("Democrat"=16, "Republican"=18)) +scale_color_manual(values =c("Democrat"="#2B83BA", "Republican"="#D73027")) +scale_fill_manual(values =c("Democrat"="#2B83BA", "Republican"="#D73027")) +theme(legend.position =c(0.25, 0.25),legend.background =element_rect(fill =alpha("white", 0.8)) )
Figure 10.2: Monthly estimates of AI Support by political party affiliation. Regression analysis indicated the Party x Time interaction was significant.
Political party affiliation does not perfectly separate AI supporters and those opposed. However, the evidence shows partisans diverging over time. Moving your eyes across Figure 10.2 from left to right shows that the series began with similar levels of support for the two parties.
Beginning in November 2024, however, AI Support among Republican respondents became consistently higher. Republicans gained control of the Presidency and both houses of Congress in November 2024. My hypothesis is that Americans are more comfortable with powerful, quickly-developing technologies when their preferred party is in control.
Note that the pattern is NOT one group mirroring the other to its opposite. Support among both Democrats and Republicans fell from the April 2025 peak.
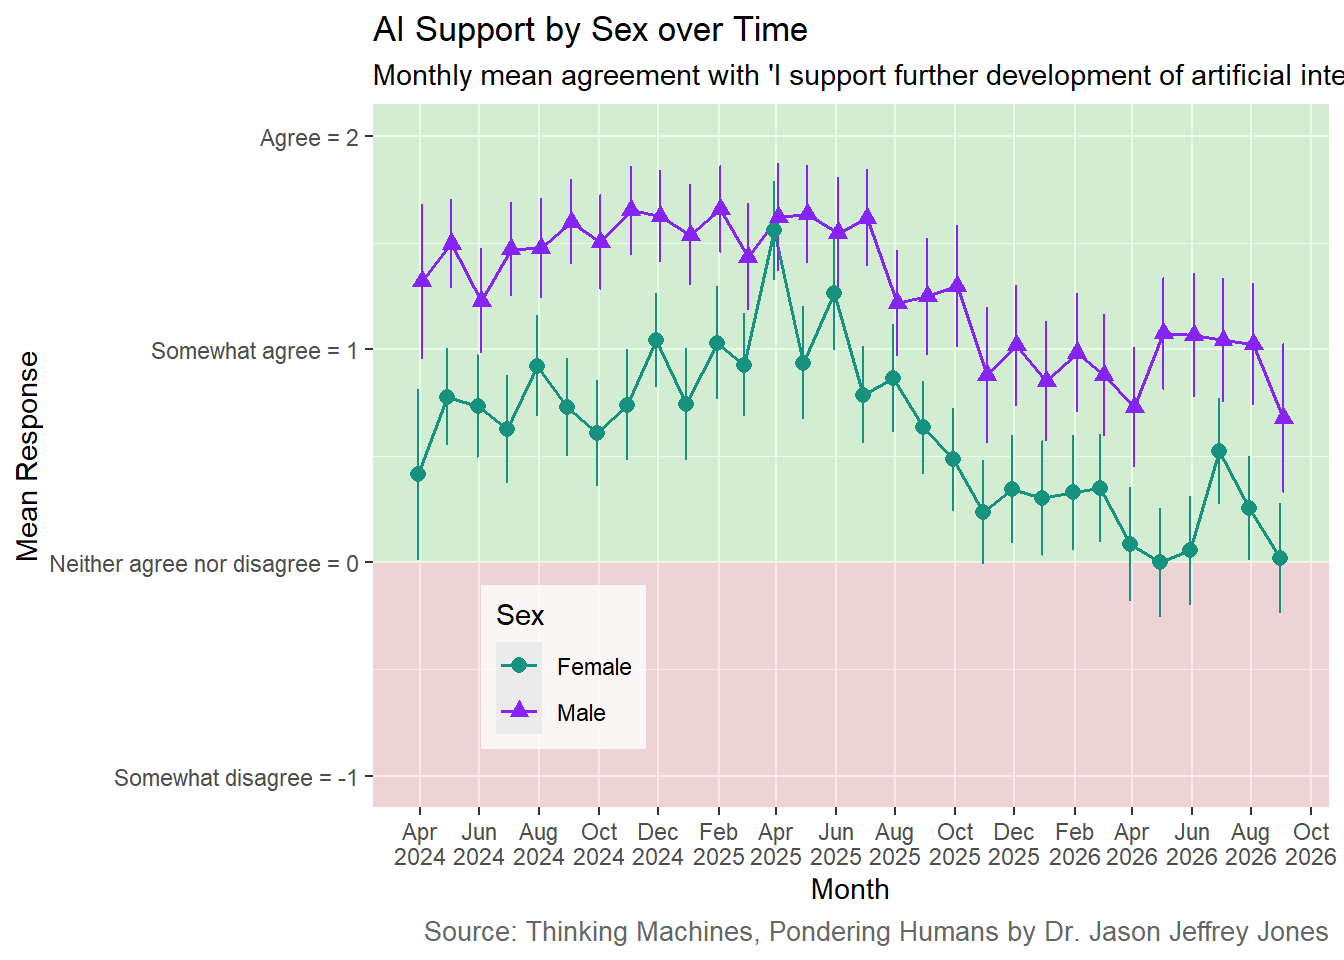
10.4.3 Male respondents consistently reported more AI Support than female respondents.
Figure 10.3: Monthly estimates of AI Support by Sex. A t-test indicated a statistically significant difference (p < 0.001).
The association between respondent Sex and AI Support has been simple and durable. Male respondents consistently reported more AI Support than female respondents.
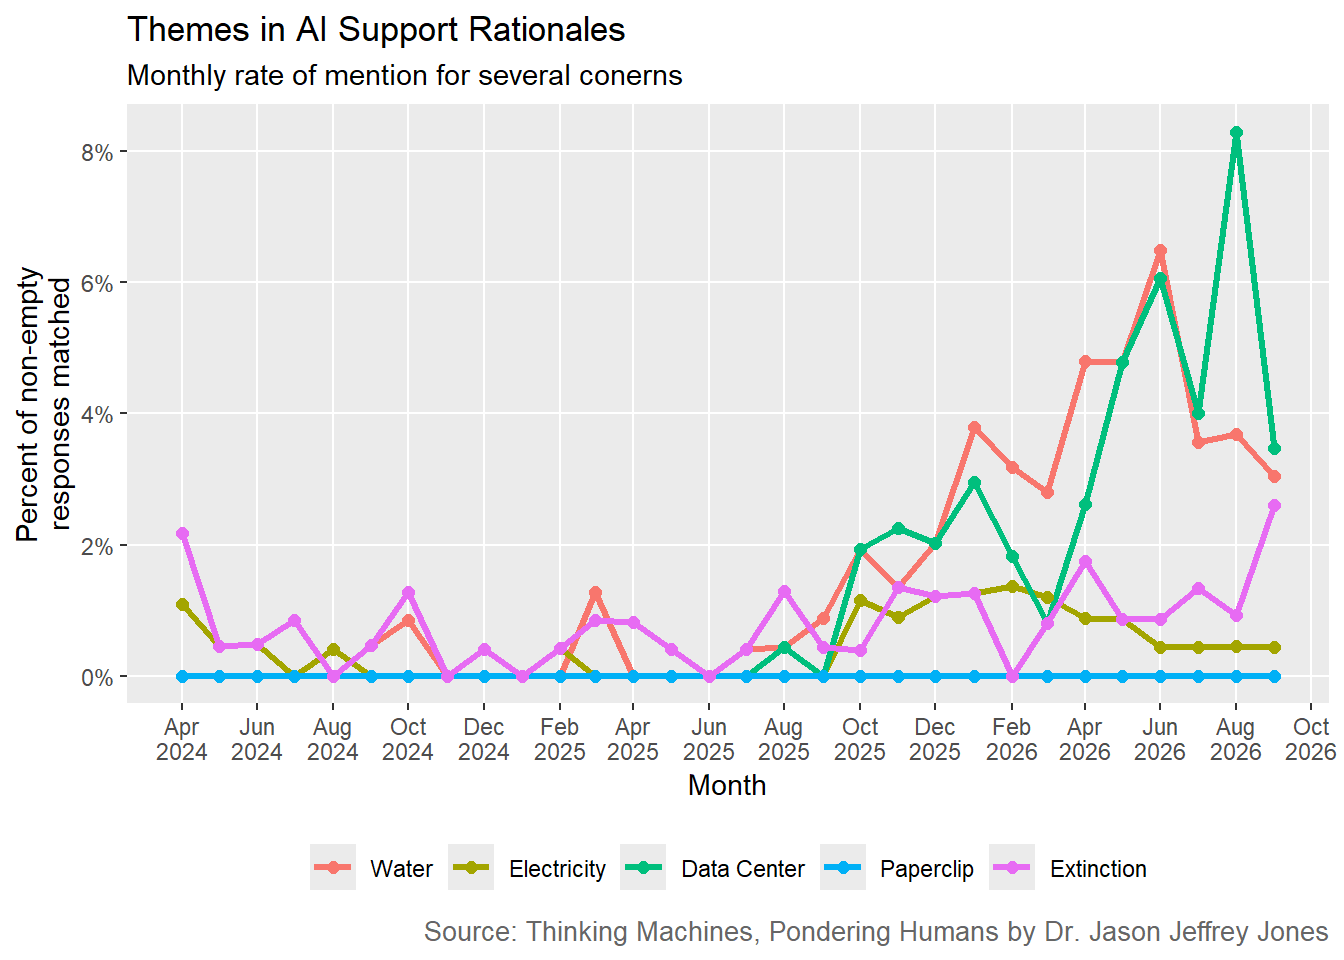
10.4.4 Concerns about water and data centers appeared later in the series.
After reporting their AI Support level, the survey asked respondents to Write 1 to 3 sentences explaining why. 6868 respondents (about 69%) wrote an explanation. Let’s look at the rate at which they mentioned particular words over time. We’ll start with concerns.
Code
# ============================================================# USER INPUT: Five regexes and their labels# ============================================================water_regex <-"\\bwater\\b"electricity_regex <-"\\belectric\\w*\\b"data_center_regex <-"\\bdata center\\w*\\b"paperclip_regex <-"\\bpaperclip\\w*\\b"extinction_regex <-"\\bkill\\w*\\b|\\bextinct\\w*\\b|\\bskynet\\w*\\b|\\bterminator\\w*\\b"regexes <-c("Water"= water_regex,"Electricity"= electricity_regex,"Data Center"= data_center_regex,"Paperclip"= paperclip_regex,"Extinction"= extinction_regex)# ============================================================# Prepare data# ============================================================textRegexData <- aiDaily %>%select(Month, Text_Response) %>%mutate(Text_Response_Clean =str_squish(Text_Response) ) %>%filter(!is.na(Text_Response_Clean), Text_Response_Clean !="",!is.na(Month) )# ============================================================# Calculate empirical monthly proportions# ============================================================# Evaluate all five regexes against the text columnmatches <- purrr::map( regexes,~str_detect( textRegexData$Text_Response_Clean,regex(.x, ignore_case =TRUE) ))# Combine matches with data and calculate monthly proportionstextRegexMonthly <- textRegexData %>%mutate(!!!matches) %>%pivot_longer(cols =all_of(names(regexes)),names_to ="Series",values_to ="Regex_Match" ) %>%mutate(Series =factor(Series, levels =names(regexes)) ) %>%group_by(Month, Series) %>%summarise(n_non_empty =n(),n_matches =sum(Regex_Match),prop_matches =mean(Regex_Match),.groups ="drop" )# ============================================================# Plot: Five empirical time series# ============================================================plotConcernRates <- textRegexMonthly %>%ggplot(aes(x = Month,y = prop_matches,color = Series,group = Series )) +geom_line(linewidth =1.2) +geom_point(size =2) +scale_y_continuous(labels =percent_format(accuracy =1),limits =c(0, NA) ) +scale_x_date(date_breaks ="2 months",date_labels ="%b\n%Y",minor_breaks =NULL ) +labs(title ="Themes in AI Support Rationales",subtitle ="Monthly rate of mention for several conerns",x ="Month",y ="Percent of non-empty\nresponses matched",caption = book_source_caption,color =NULL ) +#theme_minimal(base_size = 14) +theme(legend.position ="bottom",panel.grid.minor =element_blank(),plot.caption =element_text(size =10,color ="#666666",hjust =1 ) )plotConcernRates
Figure 10.4: Rates at which each theme was included in a rationale for or against AI Support.
Mentions of data center were absent until July 2025. Respondents rarely mentioned water until that same summer. Then both grew quickly. At a low level, discussions of extinction (I included Terminator and Skynet references as well) were there from the beginning. No one was explicitly concerned with being sacrificed to maximize paperclip production.
Code
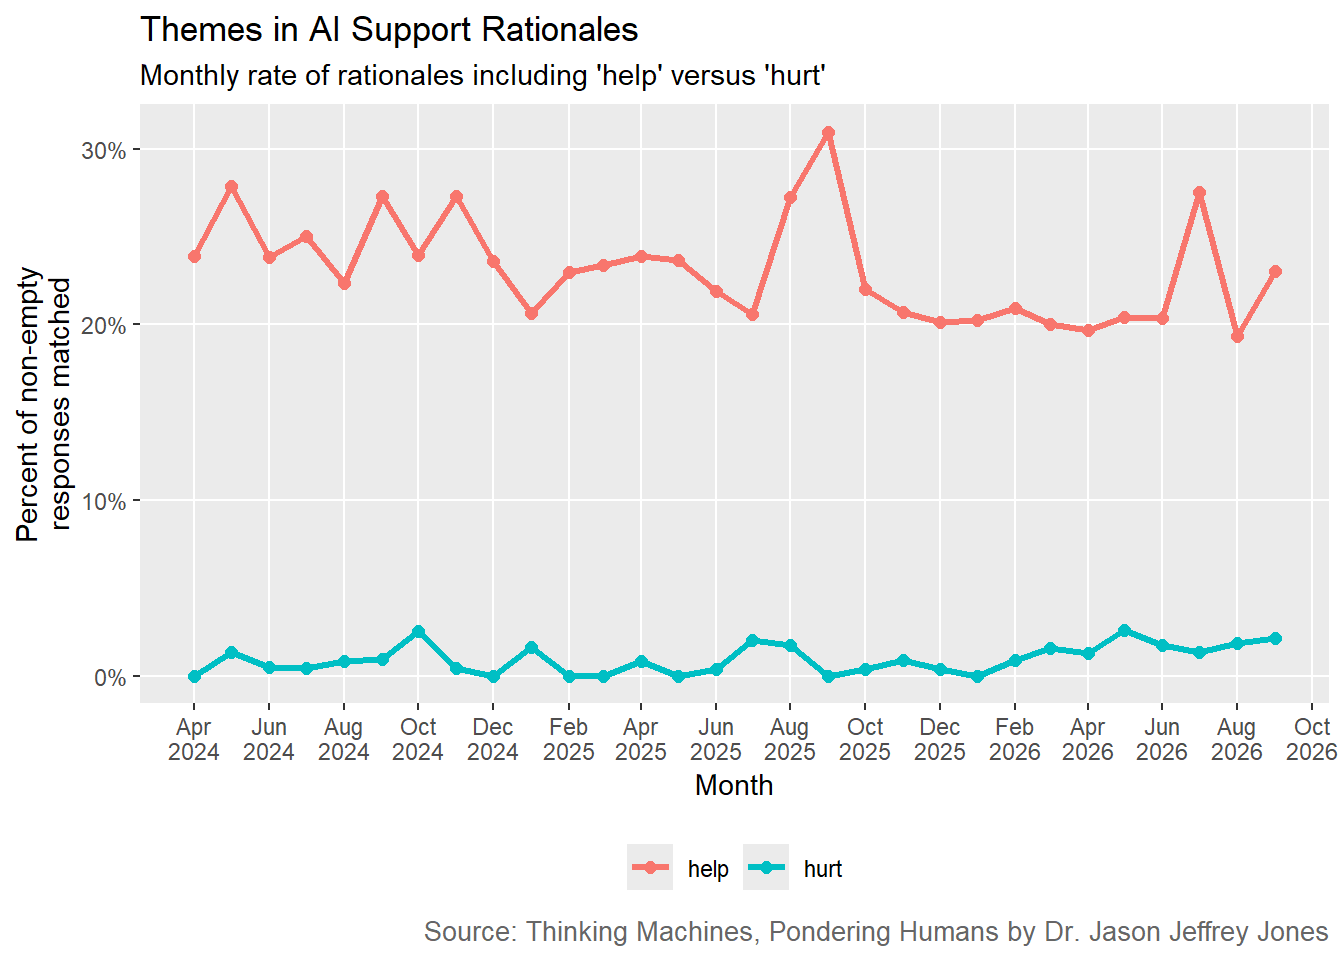
help_regex <-"\\bhelp\\w*\\b"hurt_regex <-"\\bhurt\\w*\\b"regexes <-c("help"= help_regex,"hurt"= hurt_regex)# ============================================================# Prepare data# ============================================================textRegexData <- aiDaily %>%select(Month, Text_Response) %>%mutate(Text_Response_Clean =str_squish(Text_Response) ) %>%filter(!is.na(Text_Response_Clean), Text_Response_Clean !="",!is.na(Month) )# ============================================================# Calculate empirical monthly proportions# ============================================================# Evaluate all regexes against the text columnmatches <- purrr::map( regexes,~str_detect( textRegexData$Text_Response_Clean,regex(.x, ignore_case =TRUE) ))# Combine matches with data and calculate monthly proportionstextRegexMonthly <- textRegexData %>%mutate(!!!matches) %>%pivot_longer(cols =all_of(names(regexes)),names_to ="Series",values_to ="Regex_Match" ) %>%mutate(Series =factor(Series, levels =names(regexes)) ) %>%group_by(Month, Series) %>%summarise(n_non_empty =n(),n_matches =sum(Regex_Match),prop_matches =mean(Regex_Match),.groups ="drop" )# ============================================================# Plot: Five empirical time series# ============================================================plotHelpVerusHurt <- textRegexMonthly %>%ggplot(aes(x = Month,y = prop_matches,color = Series,group = Series )) +geom_line(linewidth =1.2) +geom_point(size =2) +scale_y_continuous(labels =percent_format(accuracy =1),limits =c(0, NA) ) +scale_x_date(date_breaks ="2 months",date_labels ="%b\n%Y",minor_breaks =NULL ) +labs(title ="Themes in AI Support Rationales",subtitle ="Monthly rate of rationales including 'help' versus 'hurt'",x ="Month",y ="Percent of non-empty\nresponses matched",caption = book_source_caption,color =NULL ) +#theme_minimal(base_size = 14) +theme(legend.position ="bottom",panel.grid.minor =element_blank(),plot.caption =element_text(size =10,color ="#666666",hjust =1 ) )plotHelpVerusHurt
Figure 10.5: Rates at which respondents used the word ‘help’ versus ‘hurt’ when explaining their levle of AI Support.
Respondents were more likely to include the word help in their explanation than hurt. Let’s look at a few examples.
10.4.5 AI Help Examples
“Artificial intelligence can be useful in many different parts of life. In the medical field, it can help determine new vaccines. In technology, it can lead to better products and inventions.”
“I think AI can help perform some job tasks. As a digital marketer, I frequently use AI to help me copywrite blogs and emails I have 0 knowledge about.”
“The advancement of the technology has the potential to help a lot of people and improve the efficiency of the economy so that people don’t have to work as much to get the same amount done. Presumably, this should lead to more leisure time across the board despite the same pay.”
10.4.6 AI Hurt Examples
“TODO”
“TODO”
“TODO”
TODO write something.
10.4.7 Over time, AI Support changed differently for younger and older respondents.
Code
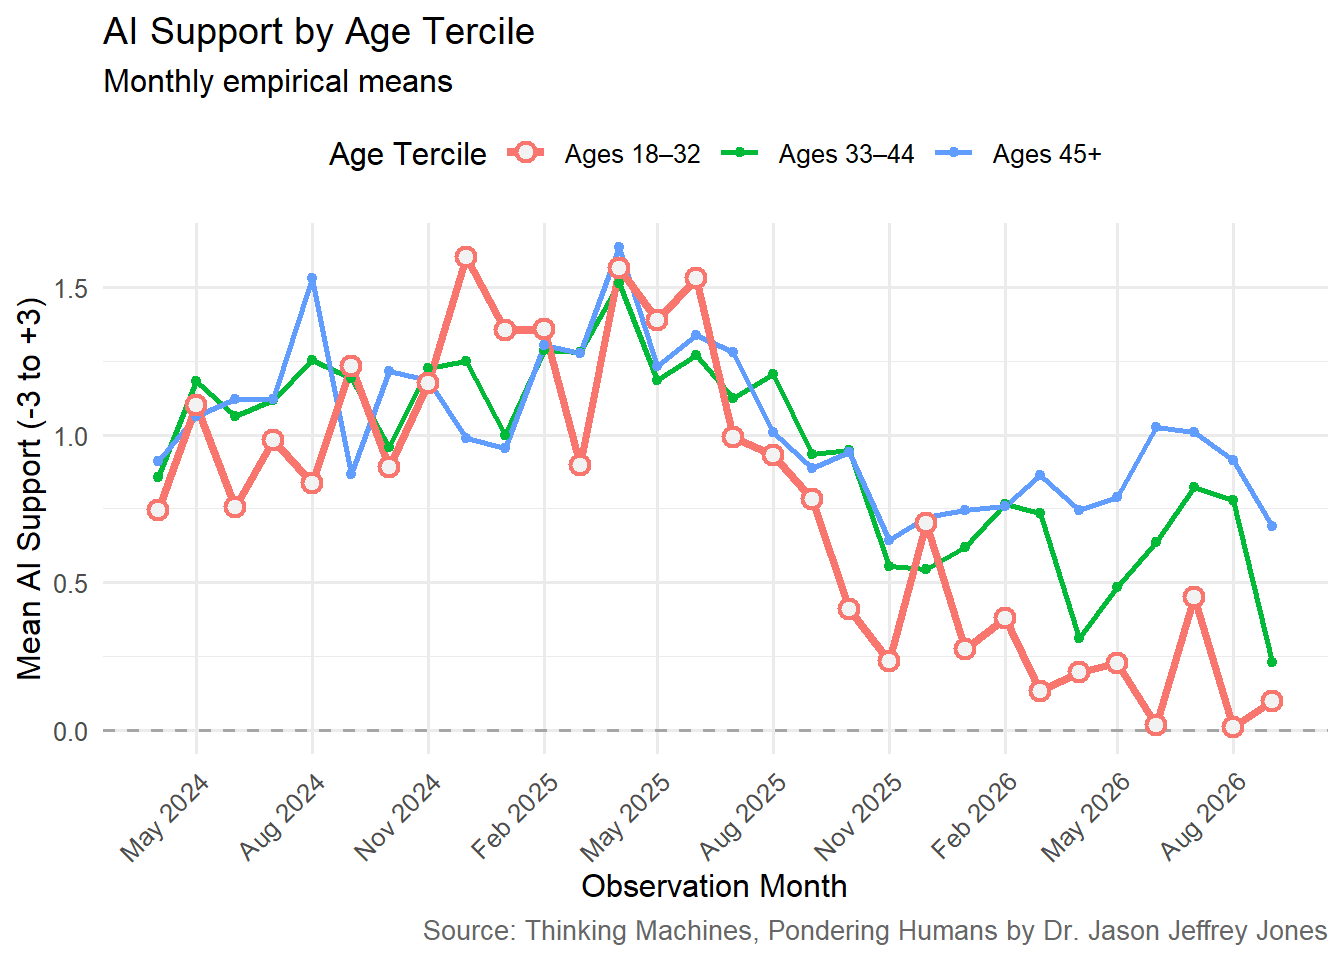
validAgeResponses = aiDaily |>mutate(Age =suppressWarnings(as.numeric(Age))) |>filter(!is.na(Age), !is.na(Support))total_N =nrow(validAgeResponses)# Compute tercile boundaries across the FULL datasetage_cuts <-quantile( validAgeResponses$Age,probs =c(1/3, 2/3),na.rm =TRUE)#print(age_cuts)# Labels reflecting the actual boundariesage_labels <-c(sprintf("Ages %.0f–%.0f", min(validAgeResponses$Age), age_cuts[1]),sprintf("Ages %.0f–%.0f", age_cuts[1] +1, age_cuts[2]),sprintf("Ages %.0f+", age_cuts[2] +1))# Assign age terciles and calculate monthly meansaiMonthlyAge <- validAgeResponses %>%filter(!is.na(Age), !is.na(Support)) %>%mutate(Age_Tercile =case_when( Age <= age_cuts[1] ~ age_labels[1], Age <= age_cuts[2] ~ age_labels[2],TRUE~ age_labels[3] ),Age_Tercile =factor( Age_Tercile,levels = age_labels ),Month =floor_date(Obs_Date, "month") ) %>%group_by(Month, Age_Tercile) %>%summarise(Mean_Support =mean(Support),n =n(),.groups ="drop" )# Plot empirical monthly meansggplot( aiMonthlyAge,aes(x = Month,y = Mean_Support,color = Age_Tercile )) +geom_hline(yintercept =0,linetype ="dashed",color ="grey65" ) +# All three seriesgeom_line(linewidth =1) +# Heavier line for youngest tercilegeom_line(data =~filter(.x, Age_Tercile == age_labels[1]),linewidth =1.5 ) +# Regular points for all seriesgeom_point(size =1.4) +# Larger, light-grey-filled circles for youngest tercilegeom_point(data =~filter(.x, Age_Tercile == age_labels[1]),shape =21,size =2.8,stroke =1.1,fill ="grey95" ) +scale_x_date(date_breaks ="3 months",date_labels ="%b %Y",minor_breaks =NULL ) +labs(title ="AI Support by Age Tercile",subtitle ="Monthly empirical means",x ="Observation Month",y ="Mean AI Support (-3 to +3)",color ="Age Tercile",caption = book_source_caption ) +theme_minimal(base_size =12) +theme(legend.position ="top",axis.text.x =element_text(angle =45,hjust =1 ),plot.caption =element_text(size =10,color ="#666666",hjust =1 ) )
Figure 10.6: Age was split into three groups of equal size (terciles). Initially, AI Support was similar for each age group. But over time, younger respondents became less supportive, both on average and relative to older adults.
The results above further emphasize a point we learned with political party affiliation. It is important to follow relationships over time. Imagine I conducted only one survey in December 2024. With just one month of results, I would be tempted to claim that younger adults more strongly supported AI development. With the context of the surrounding monthly estimates — provided by the nowcasting method — it is clear one should NOT make that proclamation.
Later, the series do appear to consistently separate. By September of 2026, it had been nine full months since a young adult AI Support estimate exceeded either of the other age groups.
Code
## Age x Time interaction: Are younger respondents becoming more negative over time?aiAgeTimeData <- validAgeResponses %>%select(Obs_Date, Days_Since_Day_One, Age, Support) %>%mutate(Age_Numeric =suppressWarnings(as.numeric(Age)),# Use decades so coefficients are readableAge_Decades = Age_Numeric /10,# Use years so time coefficients are readableYears_Since_Day_One = Days_Since_Day_One /365.25,# Center age at 39Age_Decades_Centered = (Age_Numeric -39) /10 ) %>%filter(!is.na(Support)) %>%filter(!is.na(Age_Numeric)) %>%filter(!is.na(Years_Since_Day_One))# Respondent-level Age x Time modelaiAgeTimeFit <-lm( Support ~ Age_Decades_Centered * Years_Since_Day_One,data = aiAgeTimeData)#summary(aiAgeTimeFit)#confint(aiAgeTimeFit)interaction_result <- broom::tidy( aiAgeTimeFit,conf.int =TRUE) |>filter(grepl(":", term))p_label <-if (interaction_result$p.value < .001) {"p < .001"} else {sprintf("p = %.3f", interaction_result$p.value)}interaction_caption <-sprintf("Age × Time: b = %.3f, 95%% CI [%.3f, %.3f], %s.", interaction_result$estimate, interaction_result$conf.low, interaction_result$conf.high, p_label)
One way to statistically test whether AI Support truly evolved differently by age group is with an interaction term in a regression. Specifically, a model that predicts AI Support provides this Age x Time interaction: Age × Time: b = 0.117, 95% CI [0.080, 0.154], p < .001.
The positive, statistically significant value indicates that as time proceeded, older adults reliably reported more AI Support relative to younger adults.
10.5 Survey Items, Respondents and Costs
10.5.1 Survey Items
The primary item measured AI Support. On a seven-point scale, respondents were asked how much they agreed with:
I support further development of artificial intelligence.
Directly after the above AI Support item, respondents were invited to explain in a free response field with the prompt:
(Optional) Write 1 to 3 sentences explaining why.
One item measured generalized trust:
Generally speaking, would you say that most people can be trusted or that you can’t be too careful in dealing with people?
Respondents chose between You can’t be too careful in dealing with people or Most people can be trusted.
How do you see yourself: are you generally a person who is fully prepared to take risks or do you try to avoid taking risks? Please choose a number, where the value 0 means: ‘not at all willing to take risks’ and the value 10 means: ‘very willing to take risks’.
Political party affiliation was surveyed with a standard format:
In politics today, do you consider yourself a Republican, Democrat, an independent or something else?
(Only those who chose ‘independent’ or ‘something else’ were asked the follow-up): As of today, do you lean more to the Republican Party or more to the Democratic Party?
10.5.2 Respondents
Respondents were recruited through Prolific Academic. I requested 11 new American adult respondents each day.
To demonstrate the demographic coverage, below I provide the Sex and Age crosstab:
Code
library(knitr)# Bin ages.demosTableAIDaily = aiDaily %>%rename(Age_Raw = Age) %>%select(Sex, Age_Raw)demosTableAIDaily = demosTableAIDaily %>%mutate(Age ="UNKNOWN" ) %>%mutate(Age =if_else(Age_Raw >=18& Age_Raw <25, "18-24", Age) ) %>%mutate(Age =if_else(Age_Raw >=25& Age_Raw <35, "25-34", Age) ) %>%mutate(Age =if_else(Age_Raw >=35& Age_Raw <45, "35-44", Age) ) %>%mutate(Age =if_else(Age_Raw >=45& Age_Raw <55, "45-54", Age) ) %>%mutate(Age =if_else(Age_Raw >=55& Age_Raw <65, "55-64", Age) ) %>%mutate(Age =if_else(Age_Raw >=65, "65+", Age) )demosTableAIDaily <- demosTableAIDaily |>mutate(Sex =if_else( Sex %in%c("Female", "Male", "Prefer not to say"), Sex,"UNKNOWN" ) )# Generate percentage per demographic bin for each survey sample.demosTableAIDaily = demosTableAIDaily %>%filter(!is.na(Sex), !is.na(Age)) %>%group_by(Sex, Age) %>%summarise(N =n() ) %>%# Add totalN.ungroup() %>%mutate(totalN =sum(N) ) %>%# Now we can divide across each row to calculate a percentage.mutate(percent =round(100* N / totalN, 0) ) %>%select(-totalN)kable(demosTableAIDaily, format ="markdown")
Table 10.1
Sex
Age
N
percent
Female
18-24
582
6
Female
25-34
1625
16
Female
35-44
1349
14
Female
45-54
973
10
Female
55-64
583
6
Female
65+
296
3
Female
UNKNOWN
2
0
Male
18-24
494
5
Male
25-34
1383
14
Male
35-44
1235
12
Male
45-54
695
7
Male
55-64
371
4
Male
65+
176
2
Prefer not to say
18-24
10
0
Prefer not to say
25-34
22
0
Prefer not to say
35-44
5
0
Prefer not to say
45-54
6
0
UNKNOWN
18-24
2
0
UNKNOWN
25-34
4
0
UNKNOWN
35-44
4
0
UNKNOWN
45-54
3
0
UNKNOWN
55-64
1
0
UNKNOWN
65+
62
1
10.5.3 Costs
Each respondent was paid $0.30. The median survey completion time was 1.5 minutes.
Prolific Academic charged a Service Fee equal to 33% of respondent payments.
11 respondents were recruited every day, so the total cost per day was: $4.40 = 11 * $0.30 + 11 * $0.10.
Per year, the total cost was: $1607.10 = $4.40 per day * 365.25 days per year.
About 10,000 respondents had participated as of October 2026. The total cost for these first 10,000 respondents was $4,400.00